Speculate
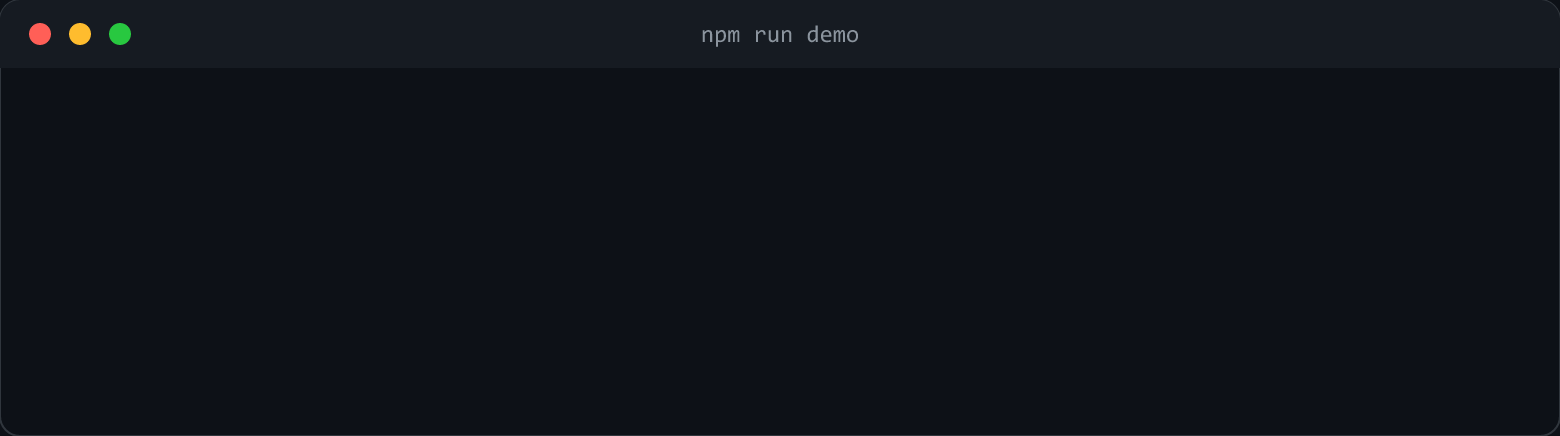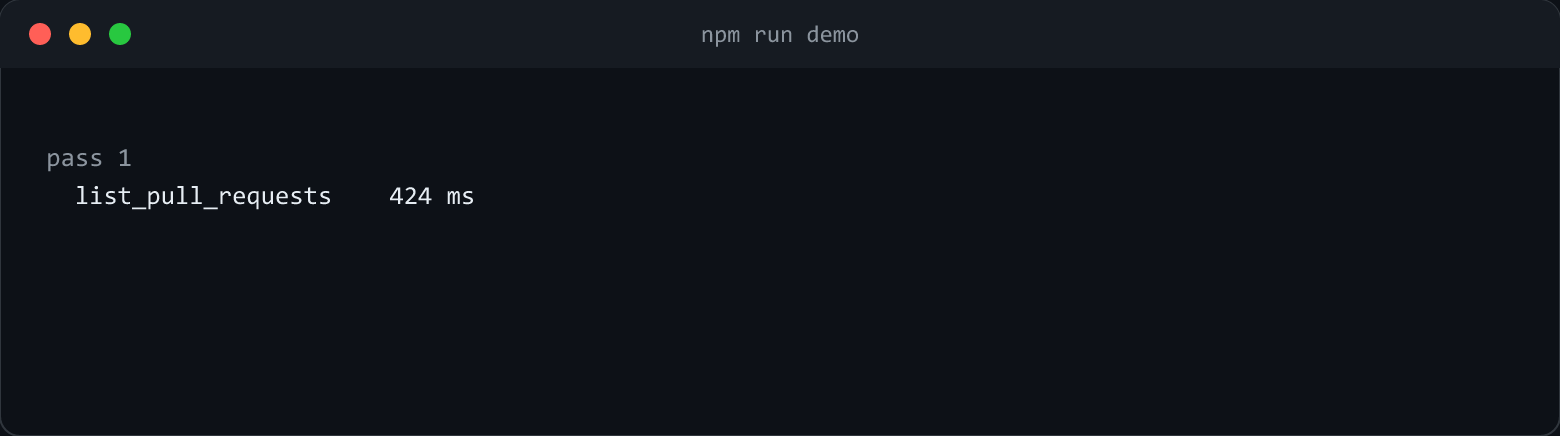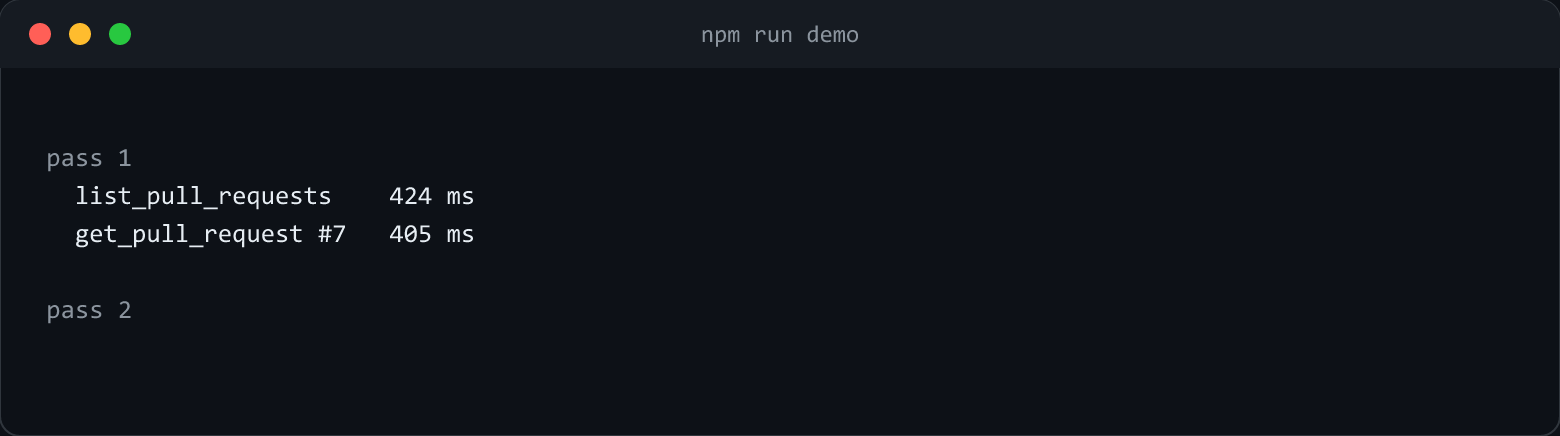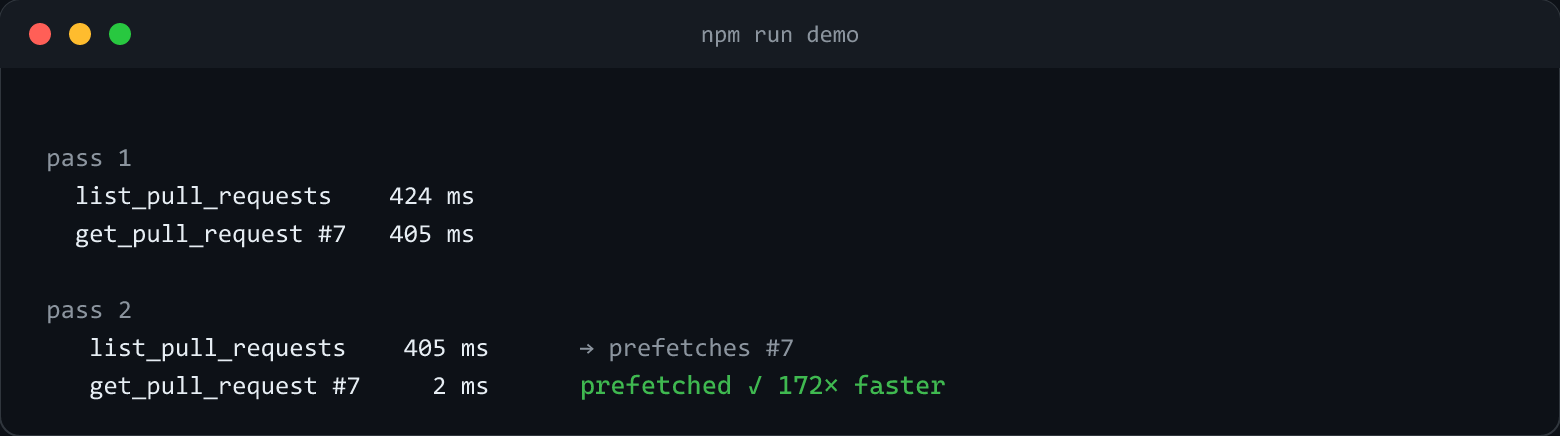
Speculative prefetching for coding agents. Speculate sits between an MCP client and its servers, learns likely read-only calls, and starts useful work early. A matching real call consumes the exact upstream result or joins the call already in progress.
With one supported native client installed, speculate launches it. With both
Claude Code and Codex installed, it asks which one to launch in an interactive
terminal. When both are installed, non-interactive shells must use speculate
run claude or speculate run codex; if neither client is available, Speculate
prints installation guidance.
The selected client starts with context-aware prefetching and automatic MCP session setup. Model-proxy observation activates only after startup verification and otherwise uses supported hooks. Native sign-in, trust, and tool permission remain with the client. See Getting started for native arguments, observation controls, and persistent MCP setup.
On how this was built
Built with heavy use of AI coding agents. Everything here is reviewed and tested, and the suite runs on Linux, macOS, and Windows, but weigh that as you would any other statement about how software was made.
-
Getting started
Launch Claude Code or Codex with context-aware prefetching, or install persistent wrappers for supported MCP servers.
-
Commands
Context-aware launch, persistent setup, authentication, diagnostics, and local memory.
-
Safety
How eligibility is restricted to tools declared read-only, and which risks that restriction does not remove.
-
Configuration
Per-server modes, allowlists, denylists, TTLs, budgets, and prediction rules.
-
Observer evidence
Measured limits and native compatibility boundaries for the context signals used by
run. -
Design
Architecture, prediction, cache semantics, release history, and benchmark methodology.
What it does
- Starts without a config file. The default learner adapts to supported MCP servers; optional per-server settings control policy, TTLs, and budgets.
- Requires a read-only declaration. Only tools with
readOnlyHint: trueare eligible. Strict mode also requires an explicit allowlist. - Preserves exact results. Speculate returns an upstream result unchanged, joins an identical call in flight, or sends the real call upstream normally.
- Keeps managed setup reversible.
offrestores registrations that still match Speculate's recorded change and reports conflicts instead of overwriting later edits.
Context-aware and persistent operation
speculate selects the installed native client; speculate run claude|codex
selects one explicitly. The native session path adds prompt,
learned cross-server transition, and supported model-stream signals. The
model-proxy path is requested by default and activated only after verification,
with startup fallback to supported hooks. The launcher preserves the client's
native account, provider, model, effort, arguments, permission policy, sandbox,
and transport selection.
See the compatibility matrix for differences
between native client surfaces.
speculate on installs persistent MCP wrappers. They learn repeated call
sequences and can use explicit rules. The registration-sync hooks installed for
Claude Code and Codex discover newly added supported servers; on alone does
not observe model or conversation context.
Evidence and limits
The maintained core qualification preserves current predictor behavior. The 1,000-record observer replay passed correctness checks but failed its speedup and speculative-waste gates for both clients. A later synthetic 60-record multi-turn diagnostic measured about 40% less warm cross-server task time for both client fixtures, but it does not establish native performance.
Native MCP transfer is verified for Claude Code and Codex. Native day-to-day speedup, native hook delivery, and live API-key routing remain unverified. The benchmark guide and observer results preserve the methods, historical results, failed gates, and limitations.
Non-goals
Speculating writes, brokering another client's credentials, general response caching, and token savings are outside scope. The intended benefit is lower wall-clock latency when a prediction is useful; workloads with poor predictions can add upstream work.